
Has Claude Opus 5.5 Actually Been Nerfed? What the Last Three Days Show
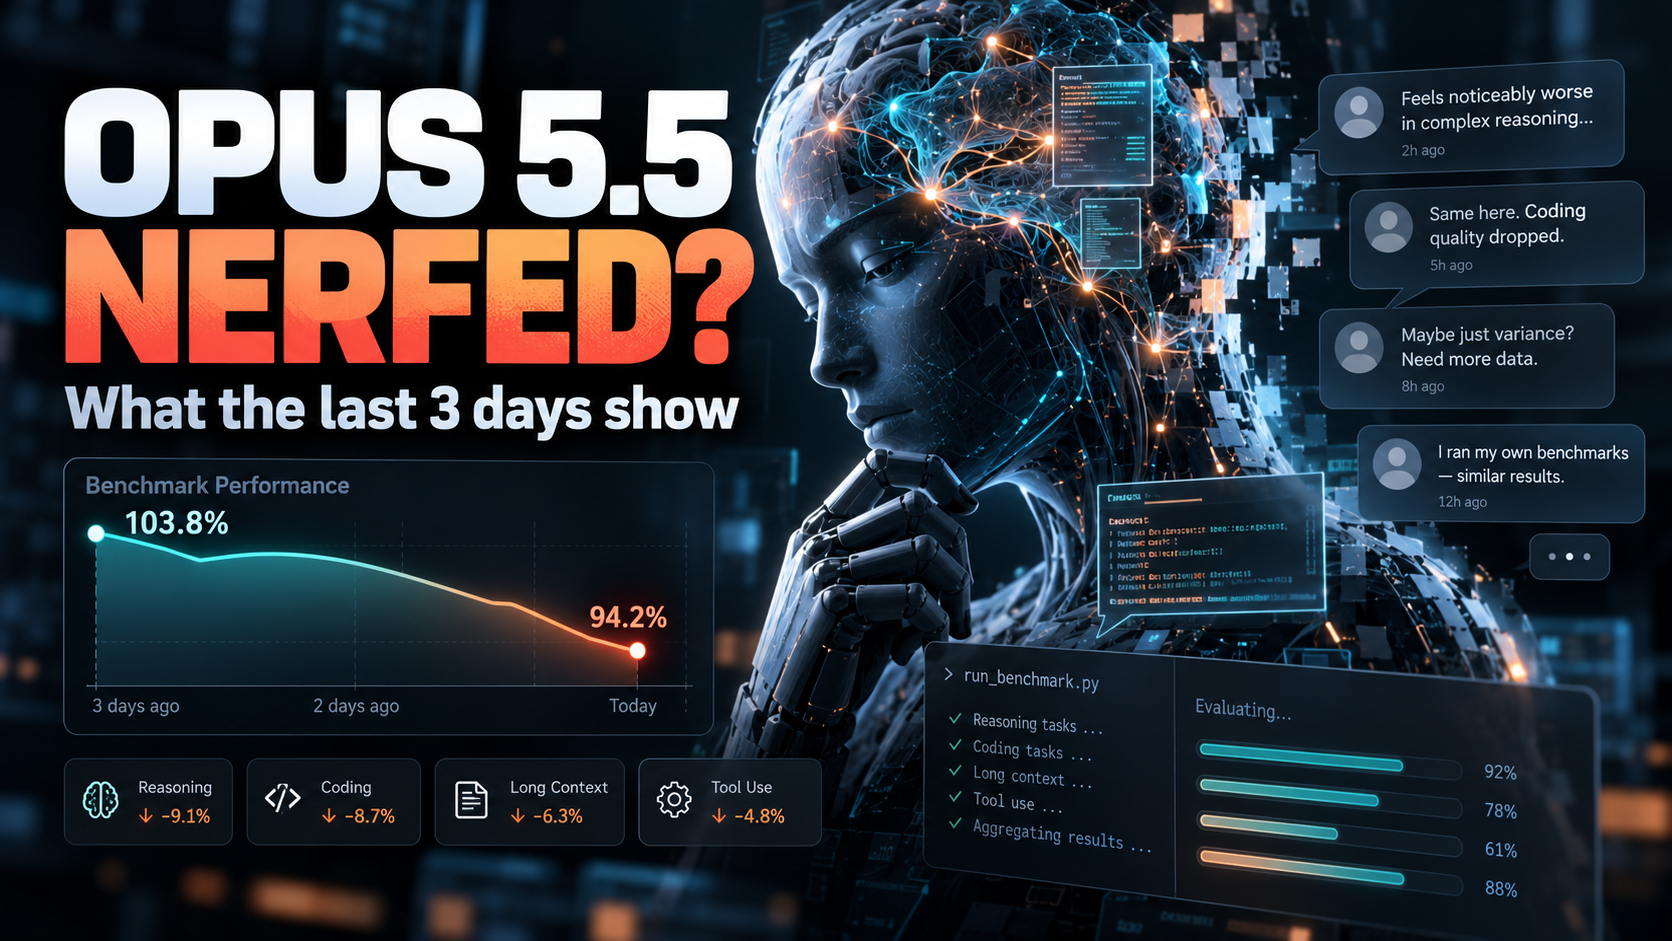
Has Claude Opus 5.5 Actually Been Nerfed?
Claude Opus 5.5 is Anthropic's current flagship Opus model, released on September 22, 2026. Over the last three days, a noticeable group of users on X has claimed that something changed.
The complaints are familiar to anyone who follows frontier AI releases: shorter answers, weaker instruction following, sloppier coding, more repair passes, higher token usage for similar work, and the return of behaviors users associate with older Claude models.
But there is an important distinction between users experiencing worse results and evidence that Anthropic actually nerfed the underlying model.
Claude Opus 5.5 just took a big drop on NerfBench. Yesterday it was scoring above launch. Today it's at 94.2%. GPT 6 Astra: 98.0% Sonnet 5.5: 100.9% GPT 6.1 Sol: 106.7% 94.2% is still inside normal variance, so we can't call it a nerf yet. But we're watching Opus 5.5 very closely.
— BridgeMind (@bridgemindai) October 2, 2026
As of October 4, 2026, there is no public evidence showing that Anthropic reduced the weights, quantization, or underlying capability of the Claude Opus 5.5 model after launch.
The complaint wave is real. A weights-level nerf is not established.
And that distinction matters because what users experience as "Claude Opus 5.5" is more than a set of model weights. Effort settings, system instructions, safety routing, context management, Claude Code, tool definitions, and other serving infrastructure all sit between the user and the underlying model.
Any of those layers can change how Claude behaves.
Why People Suddenly Think Opus 5.5 Changed
Suspicion that frontier models get "nerfed" shortly after release is nothing new.
Similar accusations have followed previous versions of Claude, GPT models, Gemini releases, and other frontier models. Launch week produces impressive examples, users become familiar with the model, workloads grow more complicated, and eventually someone asks the question:
🚨 Opus 5.5 (Launch) vs Opus 5.5 (Today) Same exact prompt But today’s output looks noticeably weaker less detail, less polish, and the overall result just doesn’t hit the same It honestly feels like Opus 5.5 got little nerfed https://t.co/l05eBB1DzG
— Salio (@Mr_Salio) October 3, 2026
"Did they make it worse?"
With Opus 5.5, however, the conversation became noticeably louder between October 1 and October 4.
One catalyst was BridgeBench's NerfBench tracker.
On October 1, Claude Opus 5.5 scored 103.8% of its measured launch performance.
On October 2, that number dropped to 94.2%.
That is a fairly large one-day swing, but there is an important detail that disappeared in many of the posts discussing it: BridgeBench itself defines results between 90% and 110% of launch performance as normal variance.
In other words, the benchmark moved down, but the people running the benchmark were not calling it evidence of a nerf.
The 94.2% number spread anyway.
At the same time, unrelated developers and Claude users were already posting that Opus 5.5 felt different. Once the benchmark number entered that conversation, the idea that "Opus 5.5 has already been nerfed" quickly gained momentum.
What Users Are Actually Complaining About
The reports are not all describing the same problem.
They tend to fall into several categories.
The nerfing of Opus 5.5 has already started You should probably cancel your Claude subscription before it renews btw
— Ahmad (@TheAhmadOsman) October 3, 2026
Coding and instruction following
The most important complaints come from people using Claude for software development.
Several developers reported that Opus 5.5 was missing instructions that it previously handled correctly, requiring additional prompts to repair its own work or taking more attempts to complete tasks.
Others reported spending more tokens while receiving lower-quality results.
These reports matter because coding is one of the areas where Claude's frontier models are most heavily used. If a model requires two or three correction passes for a task it previously completed in one, the difference is immediately noticeable.
But most of these reports have a major limitation.
They do not include the original prompt, the model effort setting, the exact Claude product being used, the Claude Code version, the previous output, or a controlled launch-week comparison.
They are experience reports rather than reproducible tests.
That does not make them meaningless. It does make them difficult to use as proof of a model change.
Claude Code and agentic work
Claude Code is where a small regression can become particularly noticeable.
An agent working across a repository may read files, modify code, run tools, inspect errors, make additional edits, and continue working for many turns.
If reasoning quality drops slightly, the result may not simply be a slightly worse answer.
It can mean more tool calls, more circular edits, more tokens, more corrections, and more time.
Recent discussions among Claude Code users have been split.
Some report Sonnet-level mistakes, unnecessary edits, circular behavior, or increased usage for tasks they believe Opus previously handled more cleanly.
Others say they have not noticed meaningful degradation at all.
That split is one of the reasons the current evidence remains inconclusive.
The return of old Claude habits
One of the stranger pieces of anecdotal evidence is linguistic.
On October 4, one developer said he considered the nerf "confirmed" because Opus 5.5 had started using the phrase "load-bearing" again, a wording habit he associated with an older version of Claude.
Other users have pointed to similar changes in style, verbosity, phrasing, or response structure.
This kind of observation is interesting because users who spend hours every day with the same model become extremely sensitive to its habits.
But a phrase is not a model identifier.
Changes in system prompts, sampling behavior, context, or surrounding infrastructure could all affect style without Anthropic replacing or weakening the underlying model.
If many unrelated users begin noticing the same old behaviors at the same time, that is worth watching.
It is not proof by itself.
Before-and-after creative tests
A few users have tried to provide more concrete comparisons.
On October 4, Leonel Meque shared two motion-design results from the same project and effort level, comparing an earlier Opus 5.5 result with a newer one. He considered the newer output substantially worse.
Another user, Moki, reran an Eiffel Tower visual test against a launch-week result and came to essentially the opposite conclusion. The newer output appeared slightly more detailed.
Both are much more useful than simply posting "Claude feels dumb now."
Neither is a controlled benchmark.
That contradiction is also exactly what we should expect if normal model variance is still playing a major role.
The Strongest Evidence That Something May Have Changed
There are three reasons the reports should not simply be dismissed.
First, the complaints are coming from multiple unrelated users.
Between October 1 and October 4, developers, AI power users, and builders posted similar observations: worse instruction following, shorter or less useful responses, more repair loops, and in some cases more token usage.
Shared perception is not proof, but a pattern across independent users is more interesting than one viral complaint.
Second, NerfBench did move.
Opus 5.5 went from 103.8% of launch performance on October 1 to 94.2% on October 2.
That is a 9.6 percentage point one-day swing and puts the October 2 score 5.8% below its launch reference.
However, 94.2% remains inside BridgeBench's own 90% to 110% normal-variance range.
That distinction is critical.
The benchmark provides a quantitative signal worth watching. It does not currently provide evidence of a confirmed degradation.
Third, many complaints are similar in nature.
Users are not only saying "it feels worse." They are repeatedly describing missed constraints, unnecessary repair work, altered response length, or different agentic behavior.
The consistency makes the user-experience change harder to dismiss.
What it does not tell us is which layer changed.
The Evidence Against the Nerf Theory
Some of the strongest evidence available right now points in the opposite direction.
A developer named Sinda reran the same repo-level coding benchmark used on Opus 5.5's launch day.
The setup was unusually useful because the repository, prompt, Cursor harness, and high effort level were held constant.
On September 22, Opus 5.5 found and fixed all nine hidden defects while preserving the benchmark's restraint check.
On October 3, it again fixed all nine.
The later run was actually faster and used less context.
That test does not prove that every Opus 5.5 workload is unchanged.
It does make the idea of a universal, dramatic coding nerf much harder to support.
Moki's repeated visual test also failed to reproduce degradation.
And BridgeBench itself, despite reporting the 94.2% score that fueled much of the discussion, labels the result normal variance rather than a nerf.
There is currently no public benchmark, frozen rerun, or Anthropic artifact demonstrating a broad reduction in Opus 5.5 capability below launch.
LiveNerf Is Trying to Answer the Question Properly
One of the most interesting projects in this discussion is LiveNerf.
Rather than judging the model from screenshots or memories of good sessions, the project runs a fixed panel of tasks repeatedly through Claude Code.
The setup attempts to control variables such as the Claude Code version, effort level, tools, and memory.
More importantly, it does not declare a model nerfed because of one bad day.
Its methodology requires a baseline period followed by later comparison windows before making a formal call.
As of October 3, the project had completed its initial baseline.
Its first meaningful post-baseline verdict is not expected until later in October if data collection continues as planned.
That means one of the projects specifically designed to answer "Was Opus 5.5 nerfed?" currently does not have enough data to say yes.
That is worth remembering when individual posts are already calling the issue settled.
Has Anthropic Said Anything?
Anthropic has not publicly confirmed a post-launch reduction in Opus 5.5 capability.
More interestingly, Anthropic's own model-versioning documentation gives us a useful framework for understanding the controversy.
For current Claude model IDs, Anthropic says the model ID identifies a pinned model snapshot.
According to its documentation, Anthropic does not update the weights or configuration of an existing model ID. A changed model is released under a new model ID.
That makes a straightforward secret weights-level nerf less likely, assuming the documentation accurately describes production behavior.
But Anthropic makes another distinction that is just as important.
The model itself may be pinned while the serving infrastructure around it can change.
Anthropic specifically identifies components such as request routing, safety classifiers, and sampling logic as infrastructure that can be updated over time.
The company also acknowledges that infrastructure updates can create observable behavioral differences even when the underlying model weights remain unchanged.
That is remarkably relevant to what users are currently reporting.
Opus 5.5 Also Changed How Effort Works
There is another major variable in comparisons with previous Claude models.
Claude Opus 5.5 defaults to medium effort.
Claude Opus 5 defaulted to high effort.
Effort controls how much computation and reasoning the model spends on a request and can affect text responses, tool calls, thinking, latency, and token usage.
Anthropic itself recommends explicitly setting effort when testing Opus 5.5 rather than assuming the same configuration used with Opus 5 will produce an equivalent comparison.
This creates an obvious testing problem.
A user comparing remembered Opus 5 behavior at high effort against Opus 5.5 running at its default medium setting is not necessarily comparing equivalent reasoning budgets.
That does not explain every complaint.
It does mean effort should be controlled before calling a result evidence of degradation.
Safety Routing Can Also Change Which Model Answers
Anthropic has also documented cases where a request made while using Opus 5 or Opus 5.5 can be routed through additional safety systems.
For a narrow set of higher-risk requests, particularly in areas such as offensive cybersecurity, the request may fall back to a less capable model or be blocked.
Anthropic says most normal requests do not encounter this behavior.
But it introduces another important lesson for evaluating model quality:
The model selected in the interface is not necessarily the only component determining what response you receive.
Safety classifiers, routing systems, and surrounding product behavior can all affect the final experience.
None of this is evidence that Anthropic secretly nerfed Opus 5.5.
It is evidence that "the model feels worse" and "the model weights were downgraded" are two very different claims.
A Model Can Feel Different Even If Its Weights Never Changed
This is the part that most "AI model nerf" discussions miss.
Between claude-opus-5-5 and the answer displayed to a user are several layers that can influence behavior.
Effort and reasoning budget
Opus 5.5 uses medium effort by default.
Changing effort changes how much reasoning and output the model performs. Two tests using different effort levels are not equivalent.
Routing and safety systems
Requests may pass through classifiers and routing systems before or after reaching the model.
Changes here can influence behavior without changing the underlying model snapshot.
Context management
Long AI conversations are not equivalent to clean benchmark runs.
Claude Code automatically compacts sessions as they approach the context limit, summarizing earlier conversation history to free space.
Long debugging sessions also accumulate prompts, outputs, file contents, tool results, and previous decisions.
That means a long-running Claude Code session can behave differently from a clean launch-week test even if the model itself is identical.
If important details have been compressed into summaries or the active context has become cluttered, users may experience missed instructions or apparent forgetfulness.
Tool and harness changes
Claude Code is not simply a raw call to the Claude API.
It adds system instructions, tools, permission logic, context management, file handling, and agentic workflows around the model.
Changes to any of those components can alter how well an agent performs on a coding task.
A Claude Code regression therefore does not automatically imply an Opus 5.5 model regression.
Different product surfaces
Claude.ai, Claude Code, and direct API usage are different environments.
A degradation report that does not specify where the model was used leaves an important variable unresolved.
Someone experiencing worse Claude Code performance may be seeing something that does not reproduce through the API.
That distinction matters.
Why AI Model Nerf Reports Are So Hard to Prove
Frontier language models are probabilistic.
The same prompt can produce different outputs across runs.
One unusually bad result does not establish that the underlying model changed.
There is also a psychological problem.
People tend to remember unusually impressive launch-week results.
Those outputs are screenshotted, reposted, benchmarked, and discussed precisely because they are impressive.
Normal failures receive less attention until people begin looking for evidence of degradation.
Once "the model has been nerfed" becomes a popular theory, confirmation bias can work in both directions.
Every bad response becomes evidence of the nerf.
Every good response becomes an exception.
The surrounding software also changes constantly.
Claude Code releases new versions. Context accumulates. System instructions change. Tools change. Safety systems evolve.
If those variables are not controlled, attributing the result specifically to the model becomes extremely difficult.
And different workloads may genuinely move in different directions.
A coding benchmark, visual-generation workflow, long agentic session, and knowledge test are not measuring the same capability.
NerfBench moving downward while a frozen repository benchmark remains flat is not necessarily contradictory.
They may simply be measuring different things.
So, Was Claude Opus 5.5 Nerfed?
There is no convincing evidence yet of a weights-level nerf.
There is convincing evidence that a meaningful number of users believe their experience with Opus 5.5 changed between late September and early October.
That perception should not simply be dismissed.
But the strongest evidence currently available does not demonstrate that Anthropic reduced the capability of the underlying Opus 5.5 model.
BridgeBench's October 2 result fell to 94.2% of launch performance but remained inside its own normal-variance range.
Controlled reruns such as the frozen repository coding test have failed to reproduce a broad degradation.
Anthropic's documentation says current model IDs represent pinned snapshots whose weights and configuration do not change under the same ID.
At the same time, Anthropic explicitly says the infrastructure around those models can change and can sometimes produce observable behavioral differences.
That may ultimately be the more interesting story.
Users could be accurately detecting a change without the explanation being "Anthropic secretly replaced Opus 5.5 with a worse model."
Right now, possible change in the user experience is supported.
Confirmed model nerf is not.
What Would Actually Prove It?
The next few weeks should produce much better evidence.
A few things would materially change the verdict.
First, repeated NerfBench measurements consistently outside its stated 90% to 110% normal range would be more significant than a single 94.2% result.
Second, LiveNerf's post-baseline measurements should provide a better controlled view of whether Claude Code performance is actually declining over time.
Third, more developers could publish frozen reruns.
The useful format is simple:
Same model ID
Same effort level
Same repository or task
Same client version
Same prompt
Multiple runs
Launch-week results preserved for comparison
Fourth, any Anthropic changelog, model announcement, documentation update, or status report that aligns with the timing of the complaints would deserve close attention.
And finally, users testing Claude Code should separate long-session behavior from fresh-session behavior.
A model struggling after hours of accumulated context tells us something different from the same model failing a clean reproducible task.
Until stronger evidence appears, "Opus 5.5 has been nerfed" remains a user report rather than an established finding.
FAQ
Did Anthropic nerf Claude Opus 5.5?
There is currently no public evidence confirming that Anthropic reduced the underlying weights or capability of Claude Opus 5.5 after its September 22, 2026 launch. Users have reported worse behavior, but controlled tests and public benchmarks have not yet established a broad model degradation.
Why does Claude Opus 5.5 sometimes feel worse than it did at launch?
Several variables can change the experience without changing the underlying model, including effort settings, safety routing, long-session context management, Claude Code behavior, tool configurations, system instructions, and normal randomness between generations.
Can Anthropic change Claude without releasing a new model?
Anthropic says the weights and configuration associated with a current model ID remain fixed. However, serving infrastructure around the model can change, including routing, safety classifiers, and sampling systems. Those changes can affect observable behavior.
Does Claude Opus 5.5 use less reasoning than Opus 5?
Opus 5.5 defaults to medium effort, while Opus 5 defaulted to high. Effort affects how much reasoning and output the model uses, so comparisons should explicitly control the effort setting rather than relying on defaults.
Is Claude Code the same as using Opus 5.5 directly through the API?
No. Claude Code uses Claude models but adds its own system instructions, tools, file access, permissions, context management, and agentic workflow. A change in Claude Code performance does not automatically prove that the underlying API model changed.
How can you test whether an AI model has actually been degraded?
Use a frozen task and control as many variables as possible. Pin the model ID, effort level, client version, prompt, tools, and input data. Run the test multiple times and compare it with saved earlier results rather than memory of how the model used to behave.
When should we know more about the Opus 5.5 nerf claims?
More useful evidence should appear as repeated benchmark measurements and controlled post-launch tests accumulate. LiveNerf's later comparison windows are particularly worth watching because the project is designed to measure changes over time rather than react to individual bad outputs.